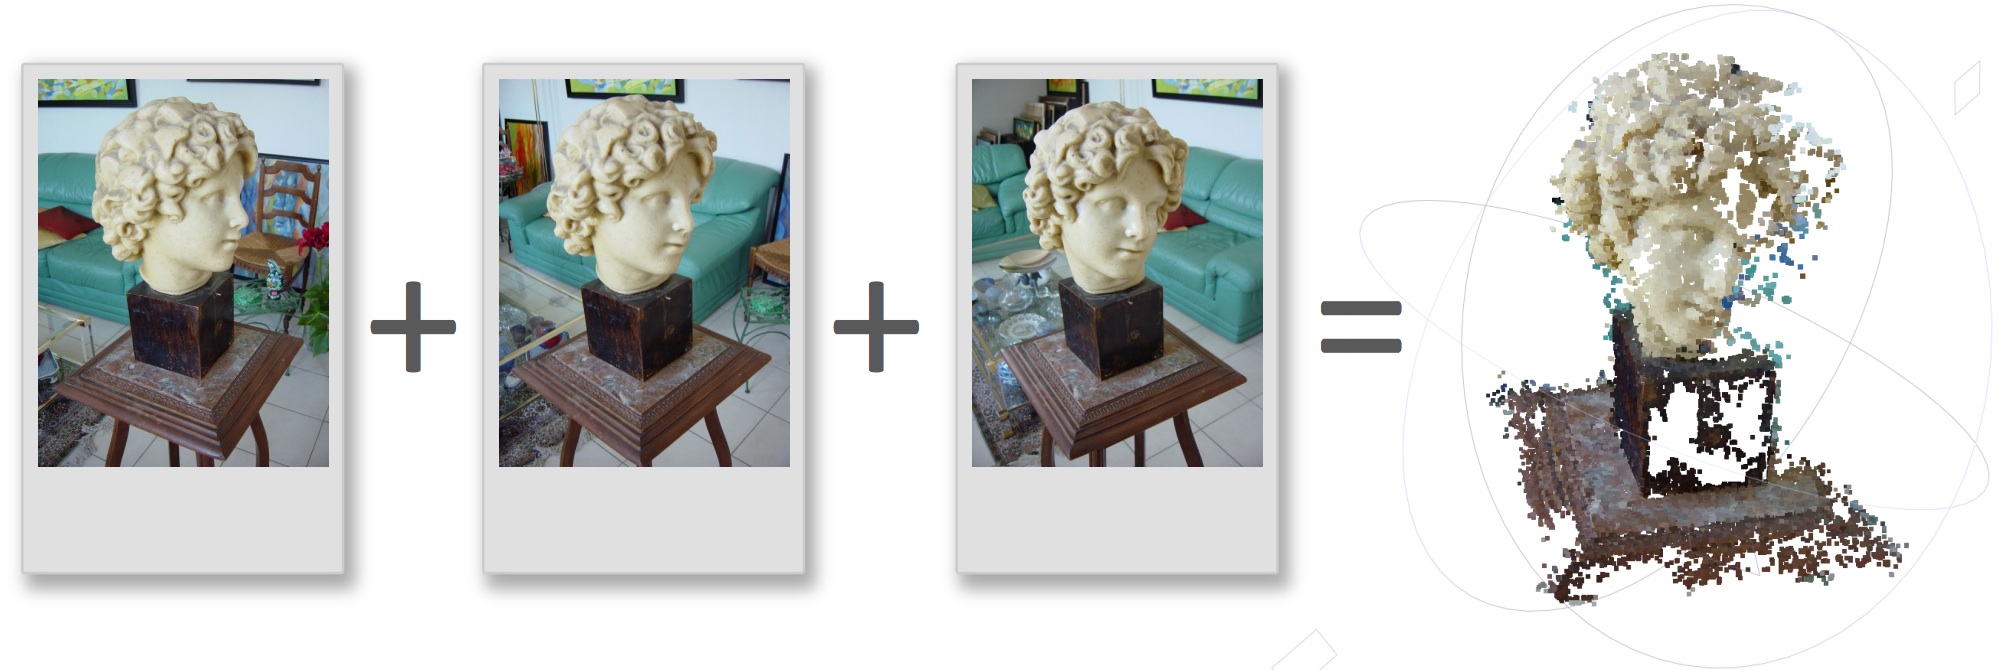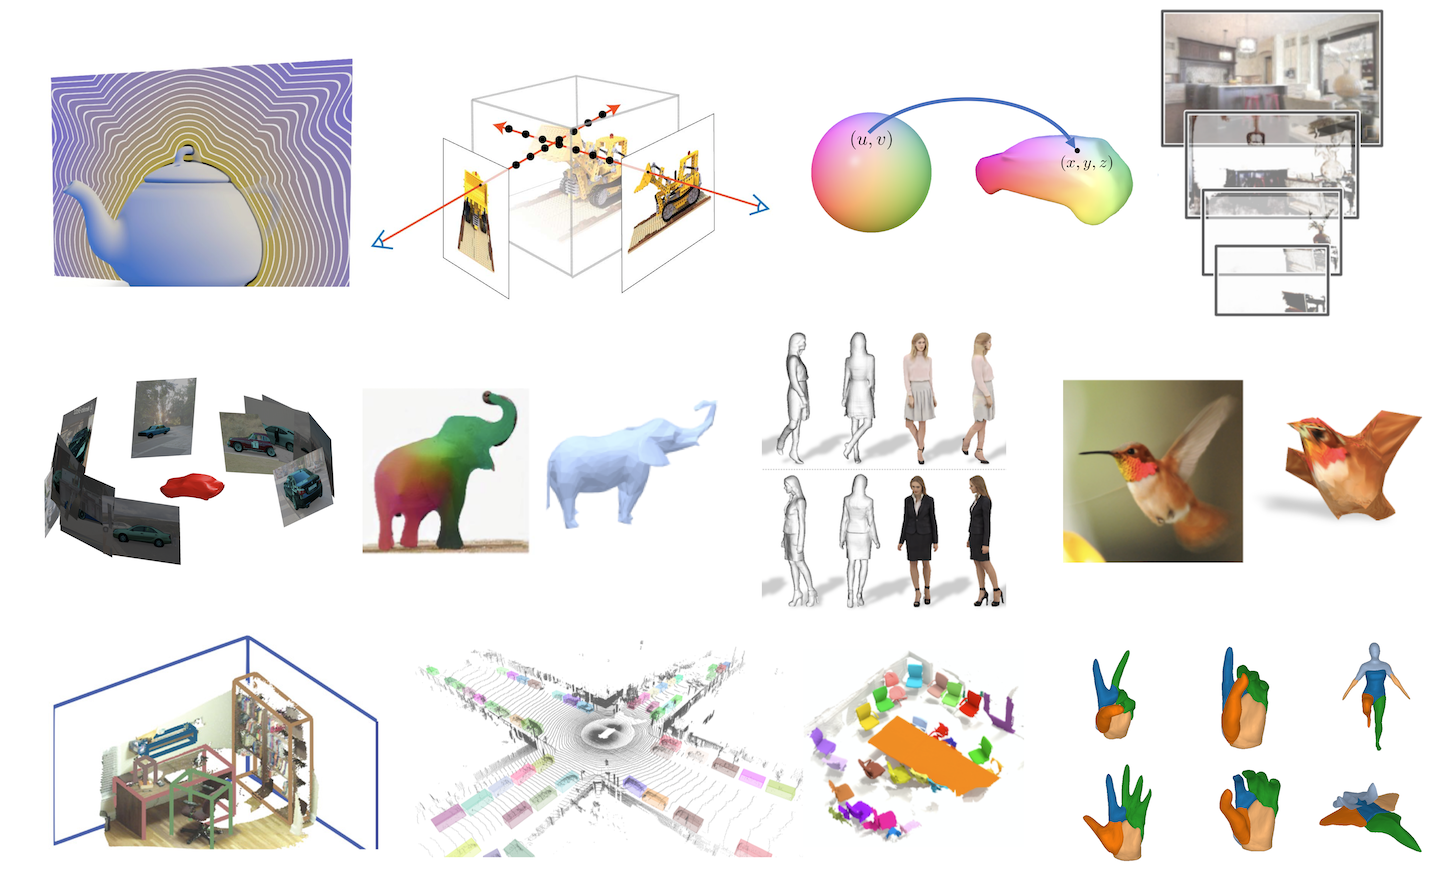
An overview of learning-based 3D vision.
Developing autonomous agents requires them to understand and interact within a 3D environment. The capability to deduce, shape, and apply 3D representations is crucial in AI for various applications, including robotic handling, autonomous driving, virtual reality, and photo editing. The ambition to comprehend 3D spaces in computer vision has made significant strides with the advent of advanced (deep) learning methods. This area aims to delve into the integration of 3D Vision with Learning-based approaches, highlighting recent breakthroughs in the field.
It covers topics including:
- Explicit, Implicit, and Neural 3D Representations
- Differentiable Rendering
- Single-view 3D Prediction: Objects, Scenes, and Humans
- Neural Rendering
- Multi-view 3D Inference: Radiance Fields, Multi-plane Images, Implicit Surfaces, etc.
- Generative 3D Models
- Shape Abstraction
- Mesh and Point cloud processing
Rendering and reconstruction
Neural surfaces
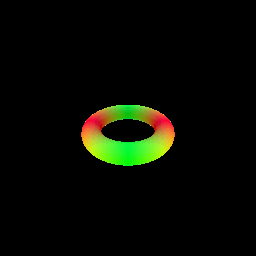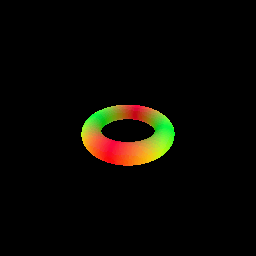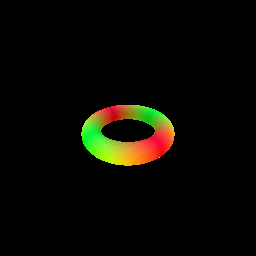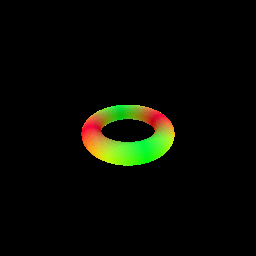
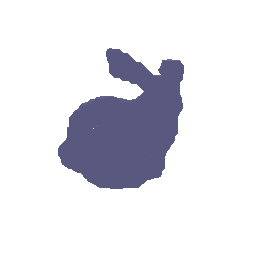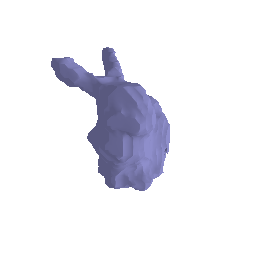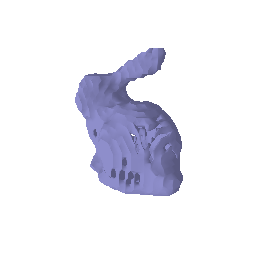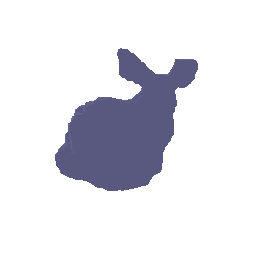
VolSDF
Phong Relighting
Render the trained SDF volume under different lighting conditions using the Phong reflection model.
Point Cloud Classification
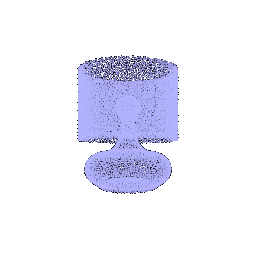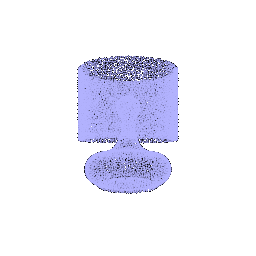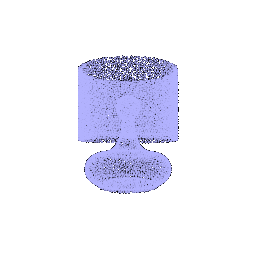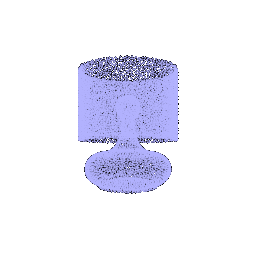
Classify point clouds across three classes: chairs, vases, and lamps.
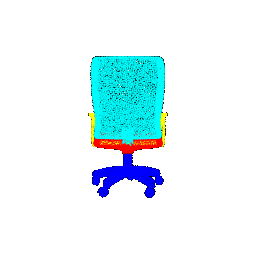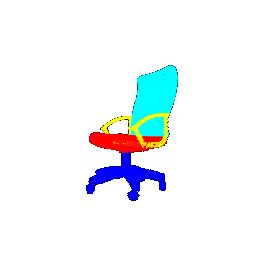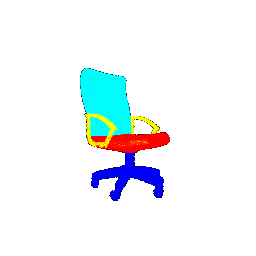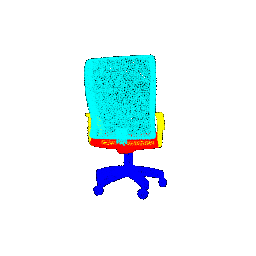
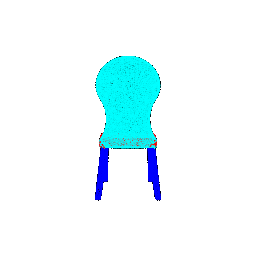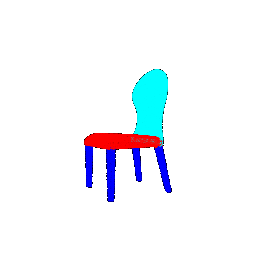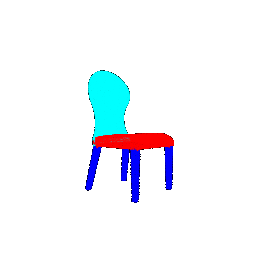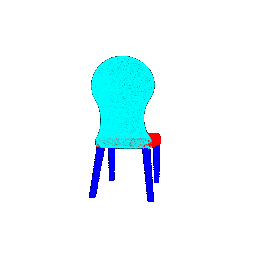
Point Cloud Segmentation
Segment chair point clouds into six semantic classes.